Plug. Play. Local AI

You should be able to pay once for your AI and use it forever, without a meter running, or someone trying to take your data.

Meet the Box
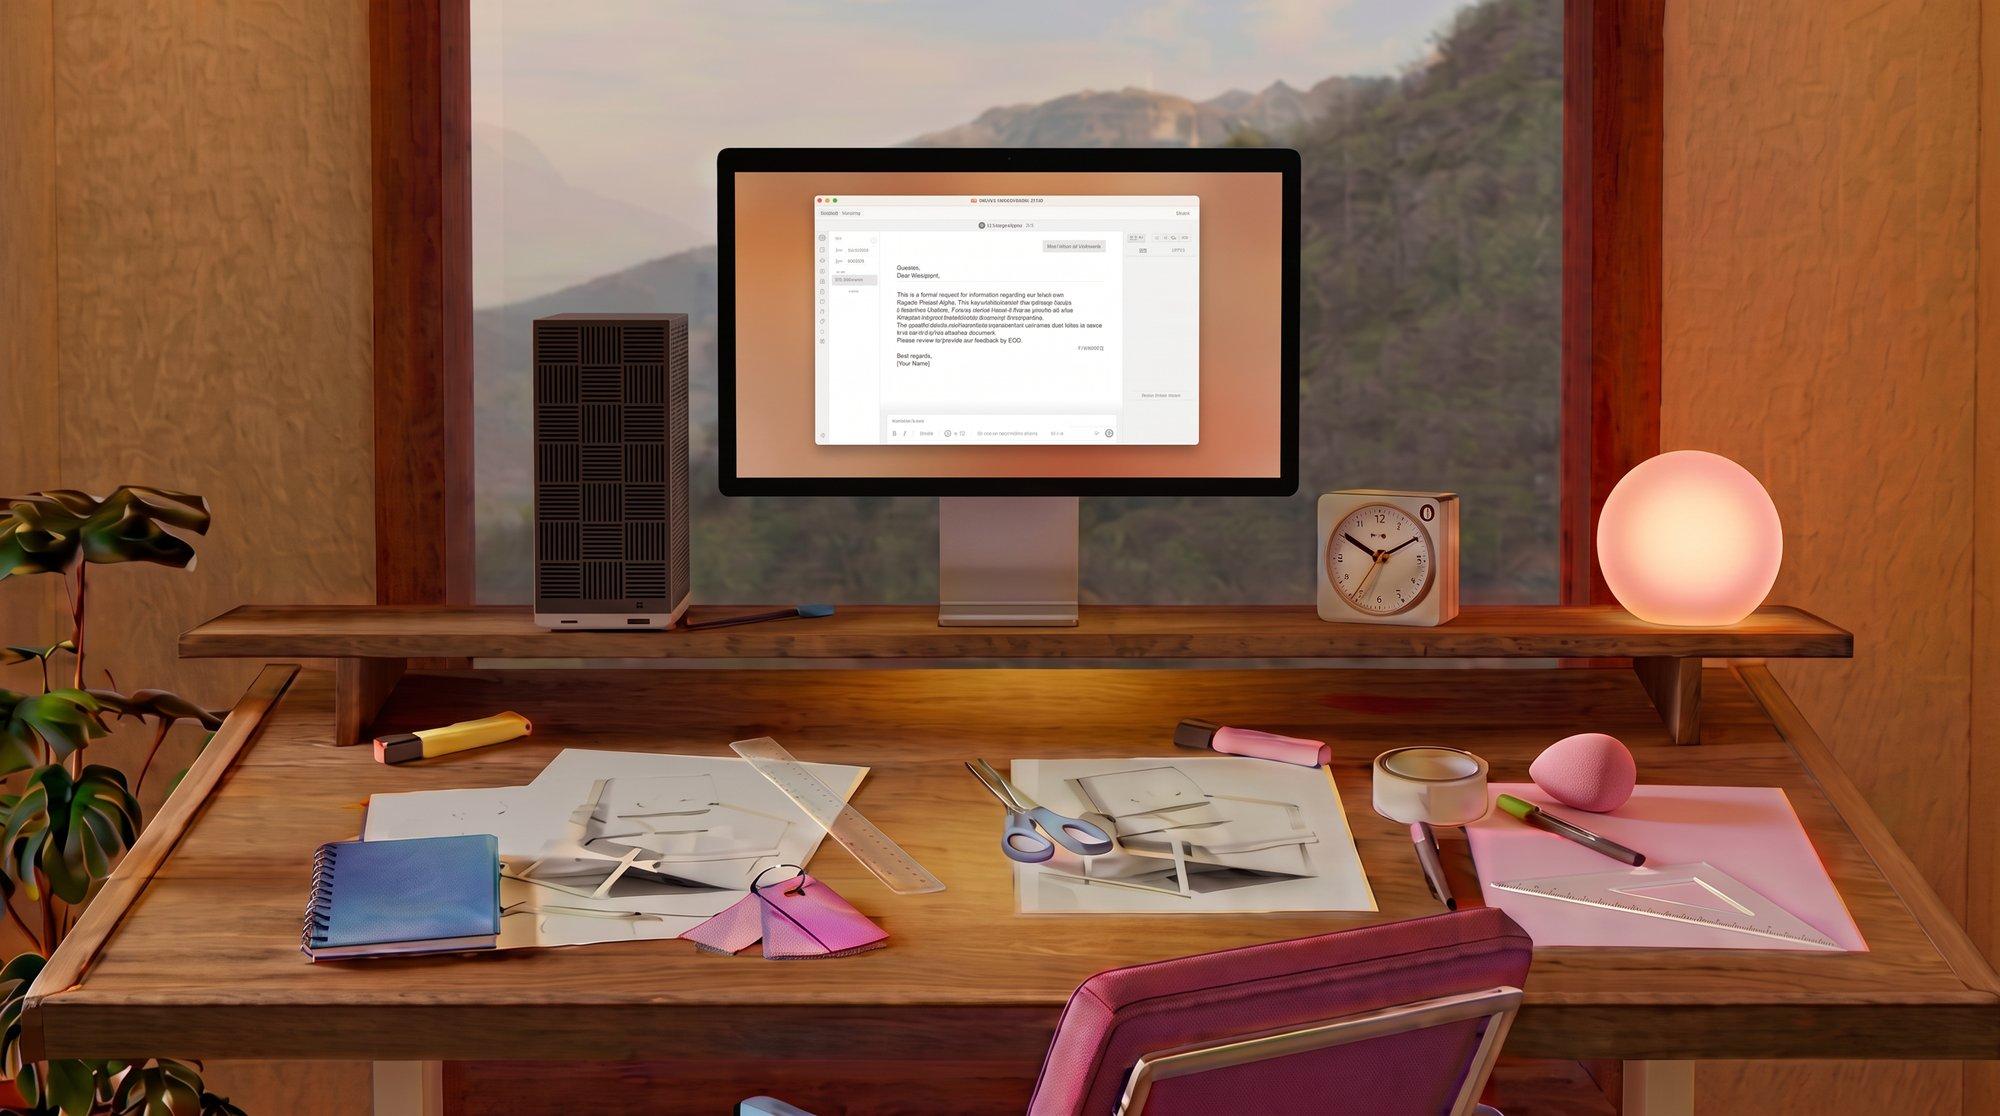
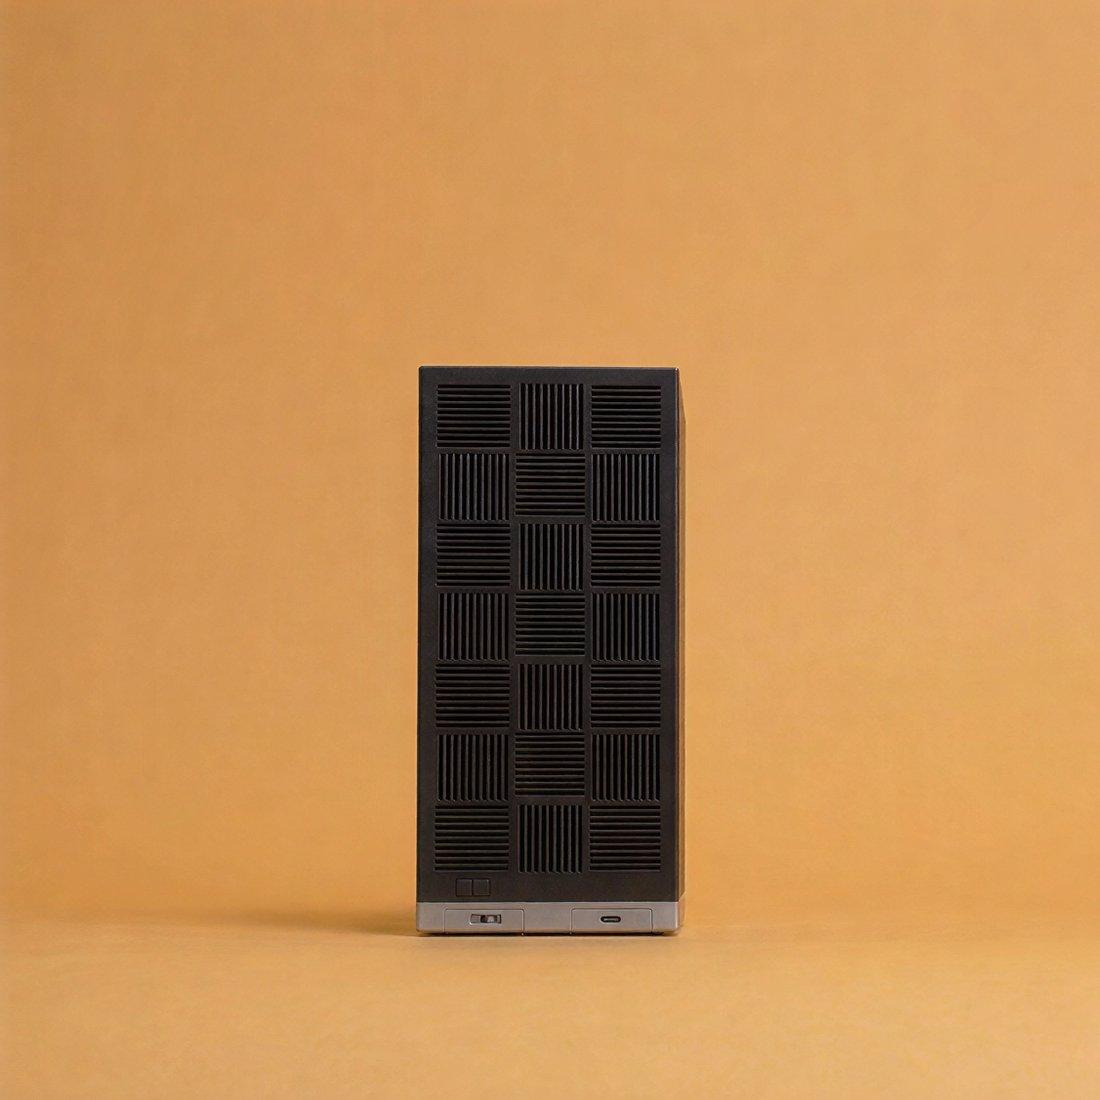
The Box, an on-prem AI appliance.

Own your AI

A crazy amount of intelligence in a mini form factor.

Cloud AI wants your data. We don’t. Everything you send to the box, stays on the box.

Some data you can't put into AI. Some you'd rather not.

A patient's chart, a client's contract, a customer's bank statements: those are off-limits. The rest, like your journal, your test results, and your emails, might be allowed, but you still hesitate before hitting paste. The Box keeps both on your desk, so you can finally use AI for all of it.

Why private means a box on your desk
Can't
  • A patient's chart
  • A client's contract
  • Bank statements
Rather not
  • Your journal
  • Your test results
  • Your emails
Your BoxStays on your desk

Your AI can change overnight. Unless it's yours.

Plans get cut. Prices go up. The model you rely on starts acting differently, and nobody asks you first. The Box runs on your desk, so nobody can change it, reprice it, or take it away.

What owning your AI means
Cloud AI plan
Usage limit
Cut in half
Your modelRetired
Your Box
Usage limitNone
Your modelYours

You shouldn't have to rent your AI.

One subscription to chat, another to code, another for the tool on top. The bills keep coming, at whatever price they set next month. The Box is one purchase. You pay once, and it's yours.

The case for paying once
JanAI subscription
FebAI subscription
MarAI subscription
AprAI subscription
MayAI subscription
JunAI subscription
And every month after
Receipt
The Box
Paid onceNo subscription

You shouldn’t have to think about how it works.

  • Unified memory
  • VRAM
  • GTT pages_limit
  • UMA frame buffer
  • ROCm
  • HIP
  • Vulkan
  • RADV
  • gfx1151
  • Kernel parameters
  • Inference engine
  • Parameters
  • Dense vs MoE
  • Quantization
  • Q4_K_M
  • GGUF
  • Context length
  • KV cache
  • Tokens/sec
  • Prefill
  • -ngl offload
  • Flash attention
  • Speculative decoding
  • MTP
  • Chat templates
  • Tool calling
  • OOM
  • Reverse proxy
  • TLS
  • VPN
  • Docker

If you have no interest in learning this stuff, that’s what we specialize in.

Faster answers, from the same hardware

We tune every model to the Box, and test every Box before it ships.

Qwen 3.6 35B (the default)
Stock settings56.7 t/s
On the Box72 t/s
Qwen 3.8 27B
Stock settings8.9 t/s
On the Box16.4 t/s

t/s = tokens per second; a token is about ¾ of a word. Measured by us on a 64 GB Box, same model and same quality both ways.

New models, without the homework

We benchmark new models on this exact hardware and add the ones that run well to the Box's Model Store.

  1. At launchQwen 3.6 35BGemma 4 26BQwen 3.6 27B
  2. Added Aug 2026Qwen 3.8 27B, with image reading
  3. NextTested on the Box first

You: plug it in and follow a few on-screen steps.

See every update we’ve shipped

Meet the pair behind arx

We wanted AI for the private stuff too. It was always capable or private, never both, until now.

Read our story

Ready to own your AI?

Meet the Box